Sovereign AI: when to self-host, and when a European gateway fits
Sovereign AI usually means control over three things: where a model runs, who operates it, and which rules apply to your data. Open weights make self-hosting a real option for some workloads. A European gateway covers the rest, including frontier models that are not published as weights.
Create a company workspaceor write to contact@standardcompute.com
Short answers
- What changed for sovereign AI this autumn?
- Mistral published the open weights of Mistral Large 4 on 29 October 2026: about one trillion parameters, built for agentic coding and defensive cybersecurity, under Mistral's own open-weight licence. Mistral's Studio platform can be deployed in Mistral's cloud, your own VPC, on-premises or a combination of these.
- When does self-hosting fit?
- When your policy says no third party may operate the model, one open model covers the workload, and you have a platform team to run GPUs, serving software and capacity. A model of Mistral Large 4's size needs a large multi-GPU deployment.
- When does a European gateway fit?
- When you need Claude, GPT and Gemini, which are not published as weights, next to open models, with one set of rules. With a Europe rule, your prompts are processed only in Europe. They enter and leave through our gateway in Finland and are served only by approved European inference endpoints, with no fallback outside Europe.
- Can we use both?
- Yes. Keep the self-hosted model for the workload that requires it and send everything else through the gateway, where you choose exactly which inference providers may handle your data.
Three ways to run sovereign AI
| Option | Who operates inference | Models | What your team runs | Fits when |
|---|---|---|---|---|
| Self-host open weights | Who operates inference: You, on your own hardware or cloud account | Models: Open-weight models, such as Mistral Large 4, GLM or DeepSeek | What your team runs: GPUs, serving software such as vLLM or SGLang, scaling and patching | Fits when: A policy forbids third-party operators and one model covers the work |
| A vendor platform in your environment | Who operates inference: The vendor's software, in your VPC or data center; Mistral Studio deploys in Mistral's cloud, your VPC, on-premises or a mix | Models: That vendor's models | What your team runs: The infrastructure under the platform | Fits when: One vendor's models cover the work and you want its tooling |
| Standard Compute, European gateway | Who operates inference: Approved European inference endpoints under a Europe rule; gateway in Finland | Models: Claude, GPT, Gemini and open models through one API | What your team runs: Rules per company, team and key in a dashboard | Fits when: You need frontier and open models under one account and one DPA |
Mistral facts from Mistral's own announcements, checked 7 November 2026. Sources are listed at the end of this page.
What self-hosting takes
With open weights, your team runs the service around the model. Mistral says Mistral Large 4 can be served with vLLM or SGLang. Your team then owns capacity planning, upgrades, monitoring, access control and the audit trail for every application that calls it.
Read the licence before you plan. Mistral publishes Mistral Large 4 under its Mistral Ecosystem Open-Weight licence, a modified MIT licence that allows commercial use and fine-tuning but requires a separate commercial licence for companies that offer the model as a service.
Self-hosting also gives you one model. Claude, GPT and Gemini are not published as weights, so a company that needs them still needs a provider.
What a European gateway gives you
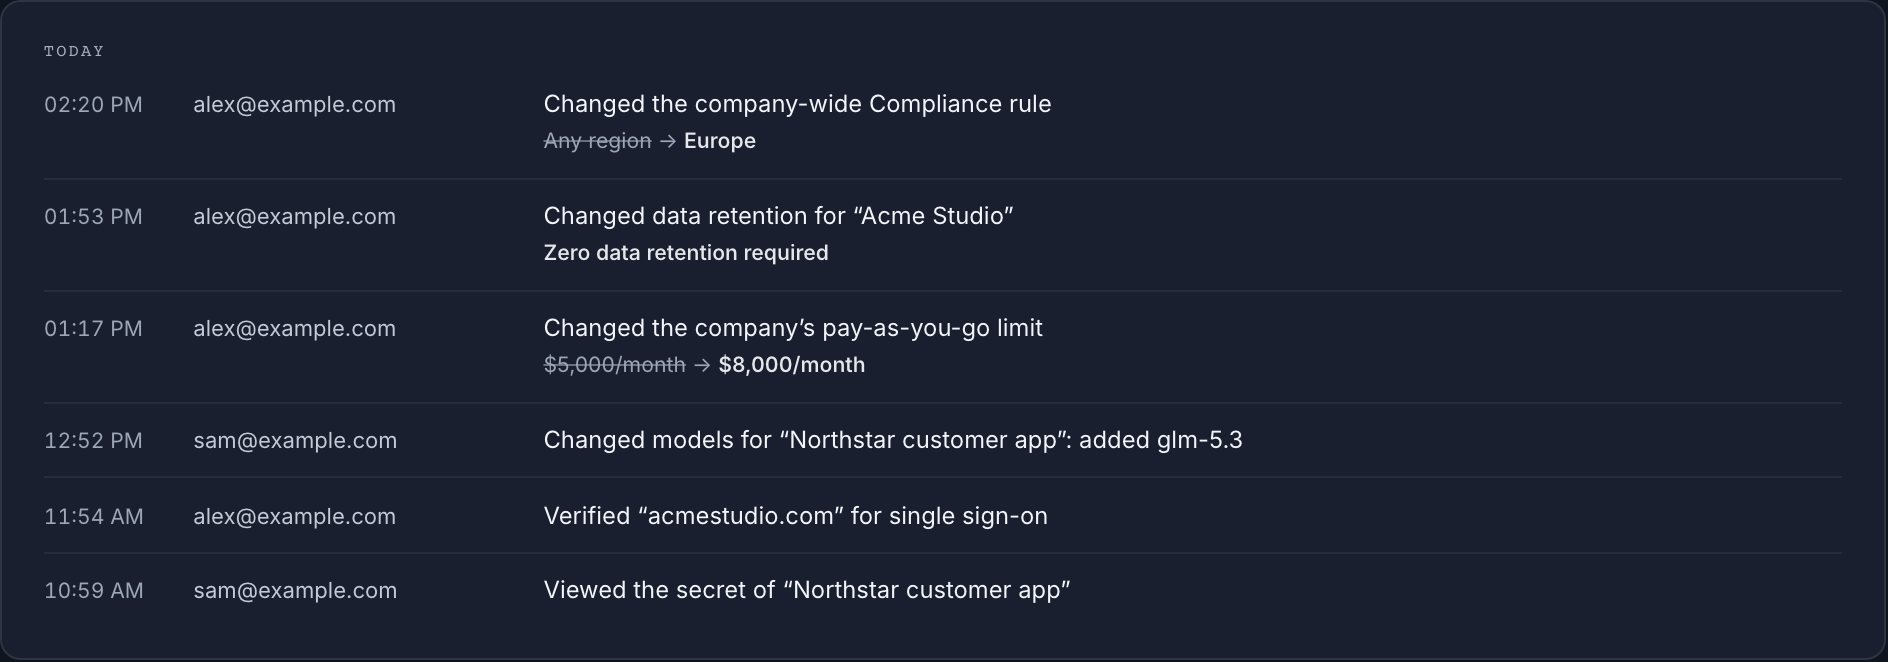
Set a Europe rule for your company, a team or a single key, and every request, including retries and fallbacks, is served only by approved European inference endpoints. If no European endpoint can serve it, the request is refused before your prompt is sent.
Our EU gateway terminates TLS and runs in Finland, and your account data is stored in Frankfurt. Choose exactly which inference providers may handle your data, for the whole company, a team or a single key. Lower levels can only narrow the rules, new providers are never added without an admin's approval, and fallbacks can never route around your list.
Turn on zero data retention for your company, a team or a key, and every request is routed only to inference endpoints that commit to keeping no copy of your data. Sign our Data Processing Agreement in the dashboard in minutes.
Which models are served in Europe, and by which providers, is listed on the European AI gateway page.
curl https://eu.stdcmpt.com/v1/chat/completions \
  -H "Authorization: Bearer $STANDARD_COMPUTE_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "anthropic/claude-sonnet-5.5",
    "messages": [{"role": "user", "content": "Classify this incident report."}]
}'Running both side by side
Many companies end up with a mix. The workload with the strictest rule runs on a self-hosted open model. Everything else, including coding agents, document work and the steps that need a frontier model, runs through the gateway with a Europe rule on the keys that need it.
A single API gives you frontier and open-source models, and it routes each step to the cheapest model that can do it and the cheapest provider fast enough to serve it. Every person and app gets a fixed monthly budget that never overruns.
Questions from IT, security and procurement
- What is a sovereign AI gateway?
- One API in front of the models your company uses, with rules for where inference runs and which providers may serve it. On Standard Compute that is a Europe rule and a provider allow-list for the company, a team or a key.
- Is self-hosting Mistral Large 4 cheaper than an API?
- It depends on volume. Self-hosting pays for GPUs whether or not they are busy, so it suits steady high volume on one model. Spiky or mixed workloads usually cost less on a gateway that sends each step to the cheapest model that can do it.
- Does "Europe" mean the EU only?
- Approved European endpoints are in the EU/EEA, the United Kingdom or Switzerland. Our EU gateway runs in Finland and your account data is stored in Frankfurt.
- What about the US CLOUD Act?
- You choose where inference runs and which providers may serve you. If your policy accepts only European-headquartered providers, a provider allow-list limits a key to them, and a model with no approved provider is refused. Our DPA is governed by Norwegian law.
- Can we keep open models on chosen applications only?
- Yes. Decide which models each key can use, so every app and every team member gets exactly the models you approve.
- Do you train on our data?
- Standard Compute never trains on your prompts or outputs. With a region rule or zero retention turned on, every request goes only to providers that commit not to train on it.
Related pages
- European AI gateway: models processed in Europe
- Open-source models for business
- Standard Compute for companies
- Security overview
- Sub-processors
- Data Processing Agreement
Sources
- Mistral AI: Mistral Large 4 open weights (29 October 2026), checked 7 November 2026
- Mistral AI: build with Studio, checked 7 November 2026
- Mistral AI: news index (dates), checked 7 November 2026
Create your company, set the Europe rule and approve the providers your policy allows.