← All models
Grok 4.20 · xAI

What does Grok 4.20 cost to run in a coding agent?

Grok 4.20 costs about $0.068 per average coding-agent request on our measured traffic, at list prices of $1.25 per million input and $2.50 per million output tokens. It holds a 2M-token context; Artificial Analysis estimates 26 for Grok 4.20 0309 v2 (Reasoning) on its Intelligence Index. Source: Artificial Analysis (artificialanalysis.ai)

List prices: xAI models and pricing, checked 2026-10-13. Request costs: Standard Compute gateway data, 79,301 coding-agent requests from 75 users, Sep 13 to Oct 12, 2026. How we compute this

Run current Claude, GPT, Gemini and open models in your agent

Or let the router send each step to the cheapest model that can do it, on providers we vet for price, uptime and speed. Plans from $19 a month.

See plans

What Grok 4.20 costs per coding-agent request

Cost at list priceGrok 4.20
Prompt under 100K tokens50% of requests, 87% of input cached$0.021
Prompt of 100K to 272K39% of requests, 88% of input cached$0.077
Prompt over 272K tokens11% of requests, 86% of input cached$0.26
Average request$0.068
100 requests$6.84
Median session16 requests; a session ends after 10 idle minutes$0.61
A month of regular usemedian of 20 users active on 5+ days$103

Each logged request priced at the vendor’s list rates for its own token counts, including cache reads and any higher rate for long prompts. Average output: 698 tokens per request.

Grok 4.20 benchmarks, speed and latency

Artificial AnalysisValueRank
Intelligence Index10 evaluations, 0 to 10026 (estimate)34 of 48
Output speedmedian95 tokens/s20 of 44
Time to first answer tokenincludes thinking time21 s9 of 44

Source: Artificial Analysis (artificialanalysis.ai). Measured variant: Grok 4.20 0309 v2 (Reasoning), speed on SpaceXAI. Fetched October 13, 2026. Rank is among the models on this site, older versions included. Artificial Analysis runs Terminal-Bench 4.0 in its own setup, so its scores differ from the tbench.ai leaderboard.

What to watch for

Every token in a prompt of 200K or more costs double, and 21% of our requests reached that line. The 2M window is useful, but filling it is expensive at those rates. The Artificial Analysis score is an estimate pending independent evaluation.

Where Grok 4.20 sits on the Artificial Analysis Intelligence Index
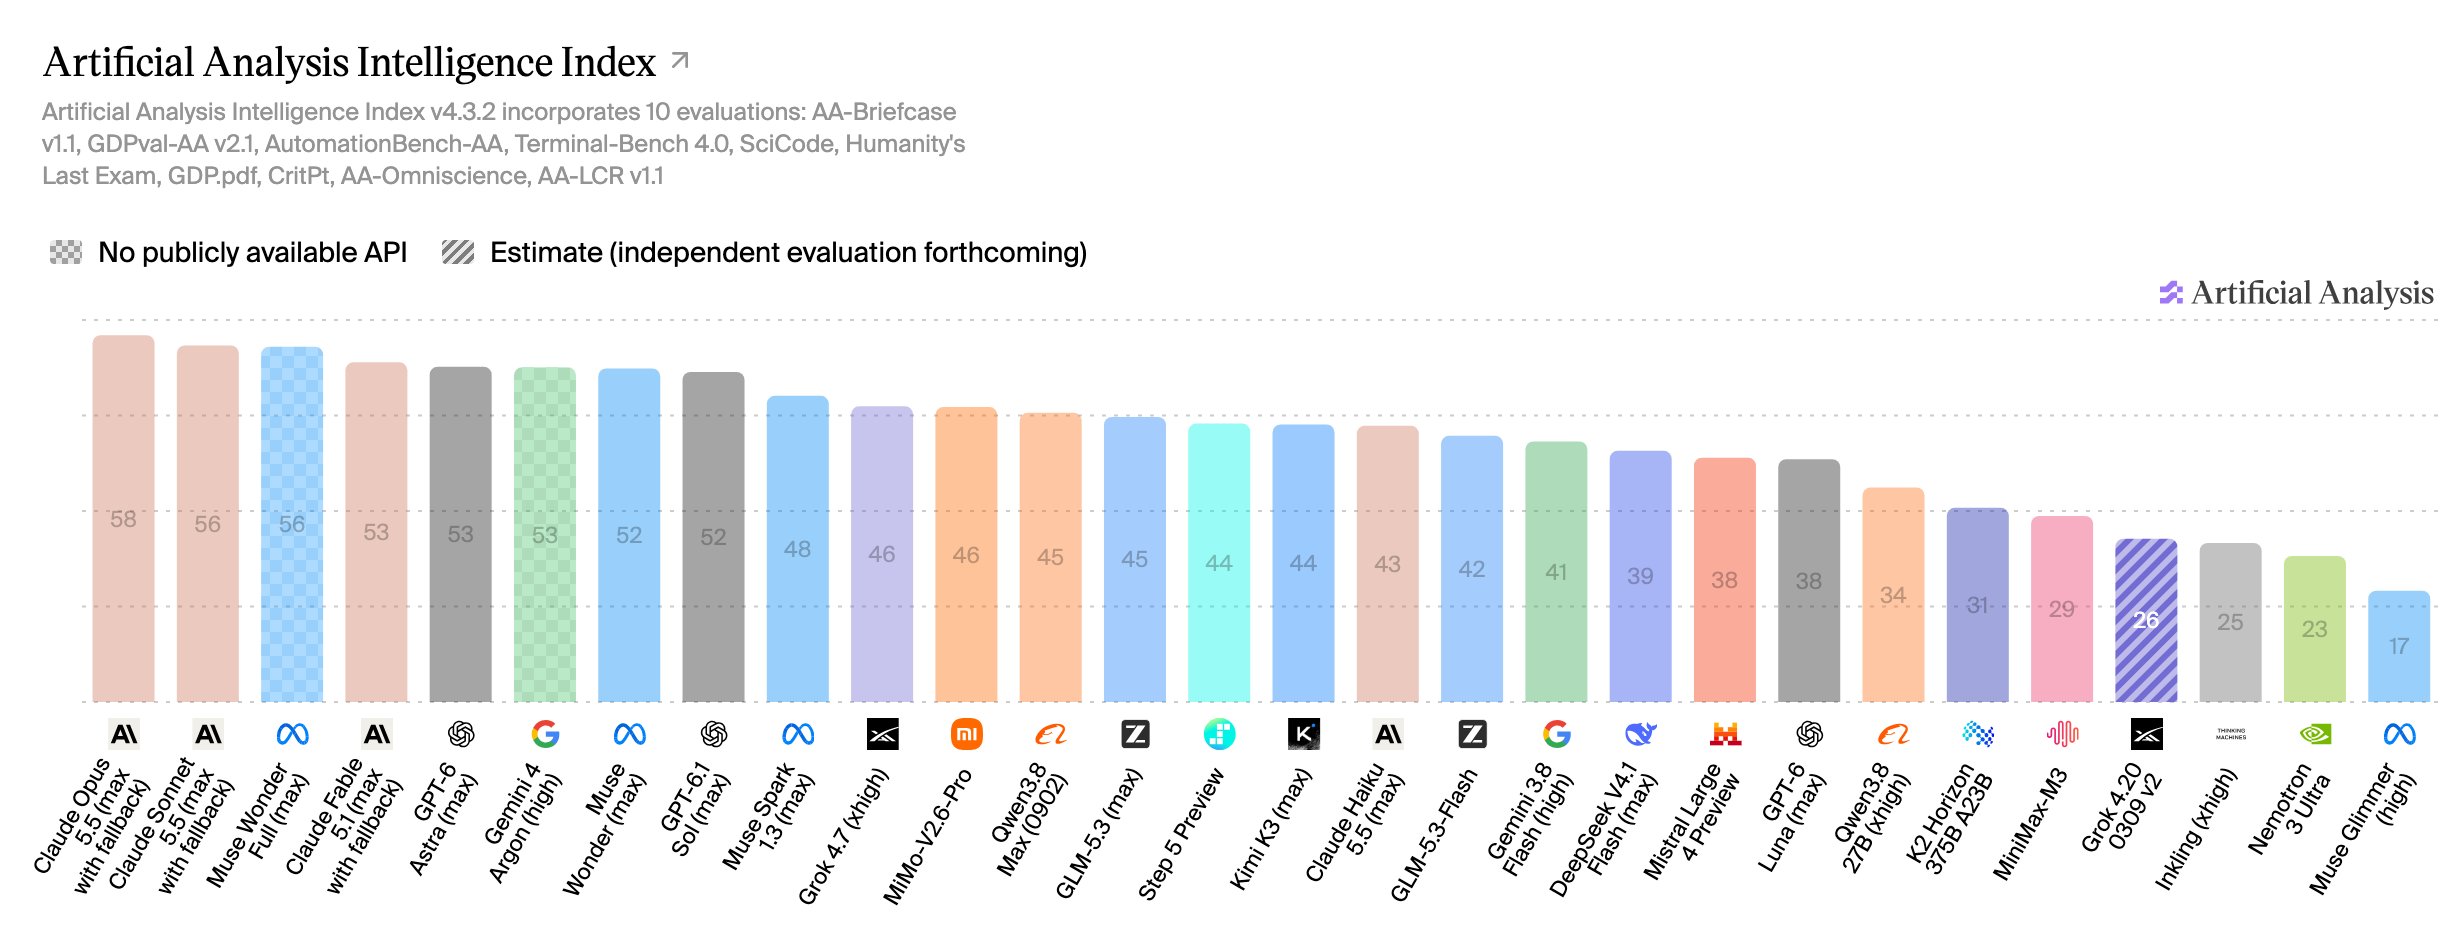
Artificial Analysis Intelligence Index bar chart with Grok 4.20 0309 v2 (Reasoning) highlighted, from artificialanalysis.ai, October 13, 2026
Artificial Analysis Intelligence Index v4.3.2, Grok 4.20 0309 v2 (Reasoning), an estimate pending independent evaluation highlighted, downloaded October 13, 2026. Source: Artificial Analysis (artificialanalysis.ai)

Leaderboards

About Grok 4.20

Grok 4.20 extends the Grok line to a 2M-token context, the largest on this hub, at $1.25/$2.50 per million tokens. It suits single runs that must hold an unusually large amount of code or documents. Artificial Analysis estimates 26 on its Intelligence Index for Grok 4.20 0309 v2 (Reasoning), pending independent evaluation, has no Terminal-Bench 4.0 result for it, and lists it as superseded; Grok 4.7 is xAI's current model. Every token in a prompt of 200K or more bills at double rates, so filling the window is expensive.

Sources: Artificial Analysis

Agents that support Grok 4.20

Runs that need more than 1M tokens of context.

Grok 4.20 FAQ

How much does Grok 4.20 cost per coding-agent request?
$0.068 on average at list price, $6.84 per 100 requests, and $0.61 for a median 16-request session. That is 79,301 real coding-agent requests (Sep 13 to Oct 12, 2026) priced at xAI's list rates; the median request sent 99,534 input tokens, 87% of input was read from cache, and requests returned 698 output tokens on average.
Does Grok 4.20 charge more for long prompts?
Yes. Prompts 200K tokens or more are billed at $2.50 per million input and $5 per million output tokens, on every token in the request including cache reads. 21% of the coding-agent requests we measured were that large.
How fast is Grok 4.20?
Artificial Analysis measures Grok 4.20 0309 v2 (Reasoning) at 95 output tokens per second, with 21 seconds to the first answer token, thinking time included, on SpaceXAI's API. Source: Artificial Analysis (artificialanalysis.ai).
Is Grok 4.20 good for AI agents?
Runs that need more than 1M tokens of context. On our scoring, which is calibrated to public benchmarks, it rates 4.7/10 for agentic ability and 5.8/10 for output quality. 2M-token context, the largest on this hub.
What is Grok 4.20's context window?
Grok 4.20 has a 2M-token context window, large enough to hold sizeable codebases or document sets in a single run. xAI is the maker.
Can I self-host Grok 4.20?
No. Grok 4.20 is a proprietary, hosted-only model from xAI. You access it through an API, such as OpenRouter, rather than running the weights yourself.
What are the downsides of Grok 4.20?
The main trade-offs: Prompts of 200K tokens or more cost double, so large contexts add up fast; No Terminal-Bench 4.0 result on Artificial Analysis; Grok 4.7 is xAI's current model for general agent work. It's strongest for runs that need more than 1M tokens of context.

Grok 4.20 compared

All 20 Grok 4.20 comparisons

The agent matters as much as the model. Which agent gets the most out of Grok 4.20? →

Current Claude, GPT, Gemini and open models run on Standard Compute

Standard Compute

Current frontier models Claude Fable 5.1 · GPT-6 Astra

More intelligence
per dollar.

Each step goes to the cheapest model that can do it, on providers we vet for price, uptime and speed, with automatic fallback when one fails.

Compliance
Opt-in rules keep a company, team or key on European or US providers
Privacy
We don’t train on your prompts or store them

Fixed monthly plans from $19 · cancel anytime

7-day fair refund Free trial, no card Billing by Stripe4,100+ agent users