The Artificial Analysis chart
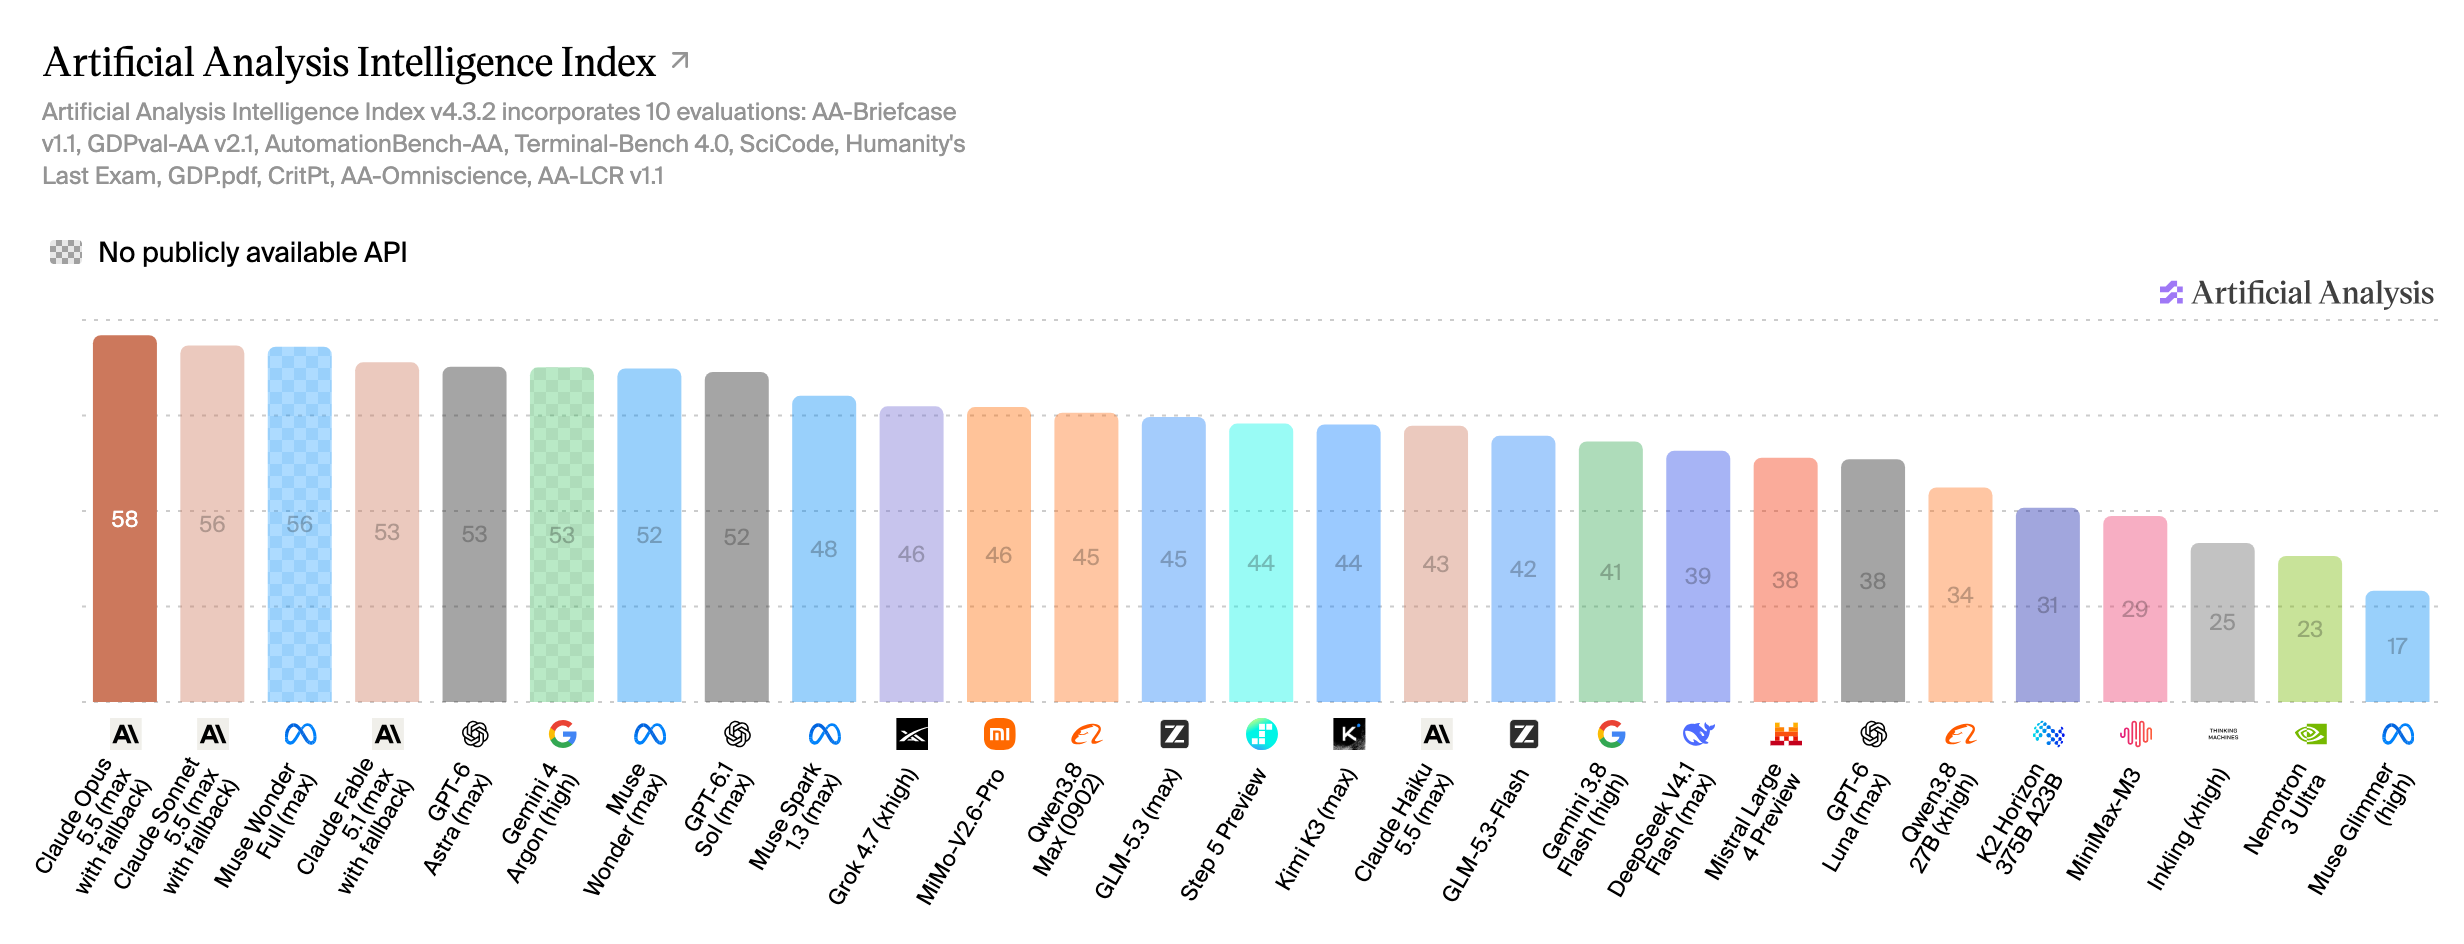
On the Artificial Analysis Intelligence Index, Claude Opus 5.5 scores highest of the models we track at 58, followed by Claude Sonnet 5.5 (56) and Claude Fable 5.1 (53). Claude Opus 5.5 costs $0.11 per average coding-agent request on our measured traffic.
Run current Claude, GPT, Gemini and open models in your agent from $19/month
See plans| Model | Intelligence IndexArtificial Analysis | Cost per requestour data |
|---|---|---|
| 1. Claude Opus 5.5max effort | 58 | $0.11 |
| 2. Claude Sonnet 5.5max effort | 56 | $0.053 |
| 3. Claude Fable 5.1max effort | 53 | $0.24 |
| 4. GPT-6 Astramax effort | 53 | $0.41 |
| 5. Gemini 4 Argonhigh effort | 53 | $0.11 |
| 6. Muse Wondermax effort | 52 | $0.11 |
| 7. GPT-6.1 Solmax effort | 52 | $0.067 |
| 8. Grok 4.7xhigh effort | 46 | $0.13 |
| 9. GLM 5.3max effort | 45 | $0.057 |
| 10. Step 5 Preview | 44 | $0.025 |
| 11. Claude Haiku 5.5max effort | 43 | $0.013 |
| 12. GPT-5.6 Terramax effort | 42 | $0.084 |
| 13. Gemini 3.8 Flashhigh effort | 41 | $0.048 |
| 14. DeepSeek V4.1 Flashmax effort | 39 | $0.0067 |
| 15. GPT-5.4xhigh effort | 39* | $0.10 |
| 16. Mistral Large 4Mistral Large 4 Preview | 38 | $0.042 |
| 17. GPT-6 Lunamax effort | 38 | $0.0041 |
| 18. DeepSeek V4 ProDeepSeek V4 Pro 0813, max effort | 36 | $0.030 |
| 19. GPT-5.3-Codexxhigh effort | 33* | $0.055 |
| 20. Gemini 3.1 ProGemini 3.1 Pro Preview | 30 | $0.095 |
| 21. Qwen3.7 Max | 29 | $0.063 |
| 22. MiniMax M3 | 29 | $0.013 |
| 23. Kimi K2.6reasoning | 27 | $0.024 |
| 24. Kimi K2.7 Code | 26 | $0.027 |
| 25. Grok 4.20Grok 4.20 0309 v2, reasoning | 26* | $0.068 |
| 26. Qwen3.7 Plus | 25 | $0.014 |
| 27. GPT-5.4 Minixhigh effort | 24 | $0.023 |
| 28. GLM 4.7reasoning | 22* | $0.017 |
| 29. DeepSeek V3.2reasoning | 21* | $0.013 |
| 30. MiniMax M2.1 | 21* | $0.0065 |
| 31. GLM 4.6reasoning | 19* | $0.015 |
| 32. Gemini 3.1 Flash Lite | 16 | $0.0082 |
| 33. DeepSeek R1 (0528)may '25 | 13* | $0.031 |
| 34. Qwen3 235B A22BQwen3 235B A22B 2507 Instruct | 12* | $0.0096 |
| 35. Llama 4 Maverick | 10* | $0.0095 |
| 36. Devstral 2 | 9 | $0.010 |
Source: Artificial Analysis (artificialanalysis.ai). Each model is measured as the variant named under it. Cost per request is ours: every one of 79,301 real coding-agent requests priced at list rates (OpenRouter's listed price for some older and open models). Methodology
| Model | Intelligence IndexArtificial Analysis | Cost per requestour data |
|---|---|---|
| Claude Fable 5superseded by Claude Fable 5.1 | 50 | $0.32 |
| GPT-6 Solsuperseded by GPT-6.1 Sol | 48 | $0.083 |
| GPT-5.6 Solsuperseded by GPT-6.1 Sol | 47 | $0.17 |
| Claude Opus 4.8superseded by Claude Opus 5.5 | 42 | $0.16 |
| GPT-5.5superseded by GPT-6.1 Sol | 38 | $0.21 |
| GPT-5.6 Lunasuperseded by GPT-6 Luna | 37 | $0.0084 |
| GLM 5.2superseded by GLM 5.3 | 34 | $0.057 |
| Gemini 3.5 Flashsuperseded by Gemini 3.8 Flash | 33 | $0.049 |
| Claude Sonnet 4.6superseded by Claude Sonnet 5.5 | 30 | $0.097 |
| Grok 4.3superseded by Grok 4.7 | 25 | $0.068 |
| Claude Haiku 4.5superseded by Claude Haiku 5.5 | 17 | $0.022 |
| Mistral Large 3superseded by Mistral Large 4 | 9 | $0.012 |
Source: Artificial Analysis (artificialanalysis.ai). Cost per request is ours. Methodology
Artificial Analysis measures each model at the reasoning effort named in its variant, usually the highest. At lower effort the same model scores lower, answers sooner and costs less. Scores marked * are Artificial Analysis estimates pending its own full evaluation.
Current Claude, GPT, Gemini and open models are included with Standard Compute