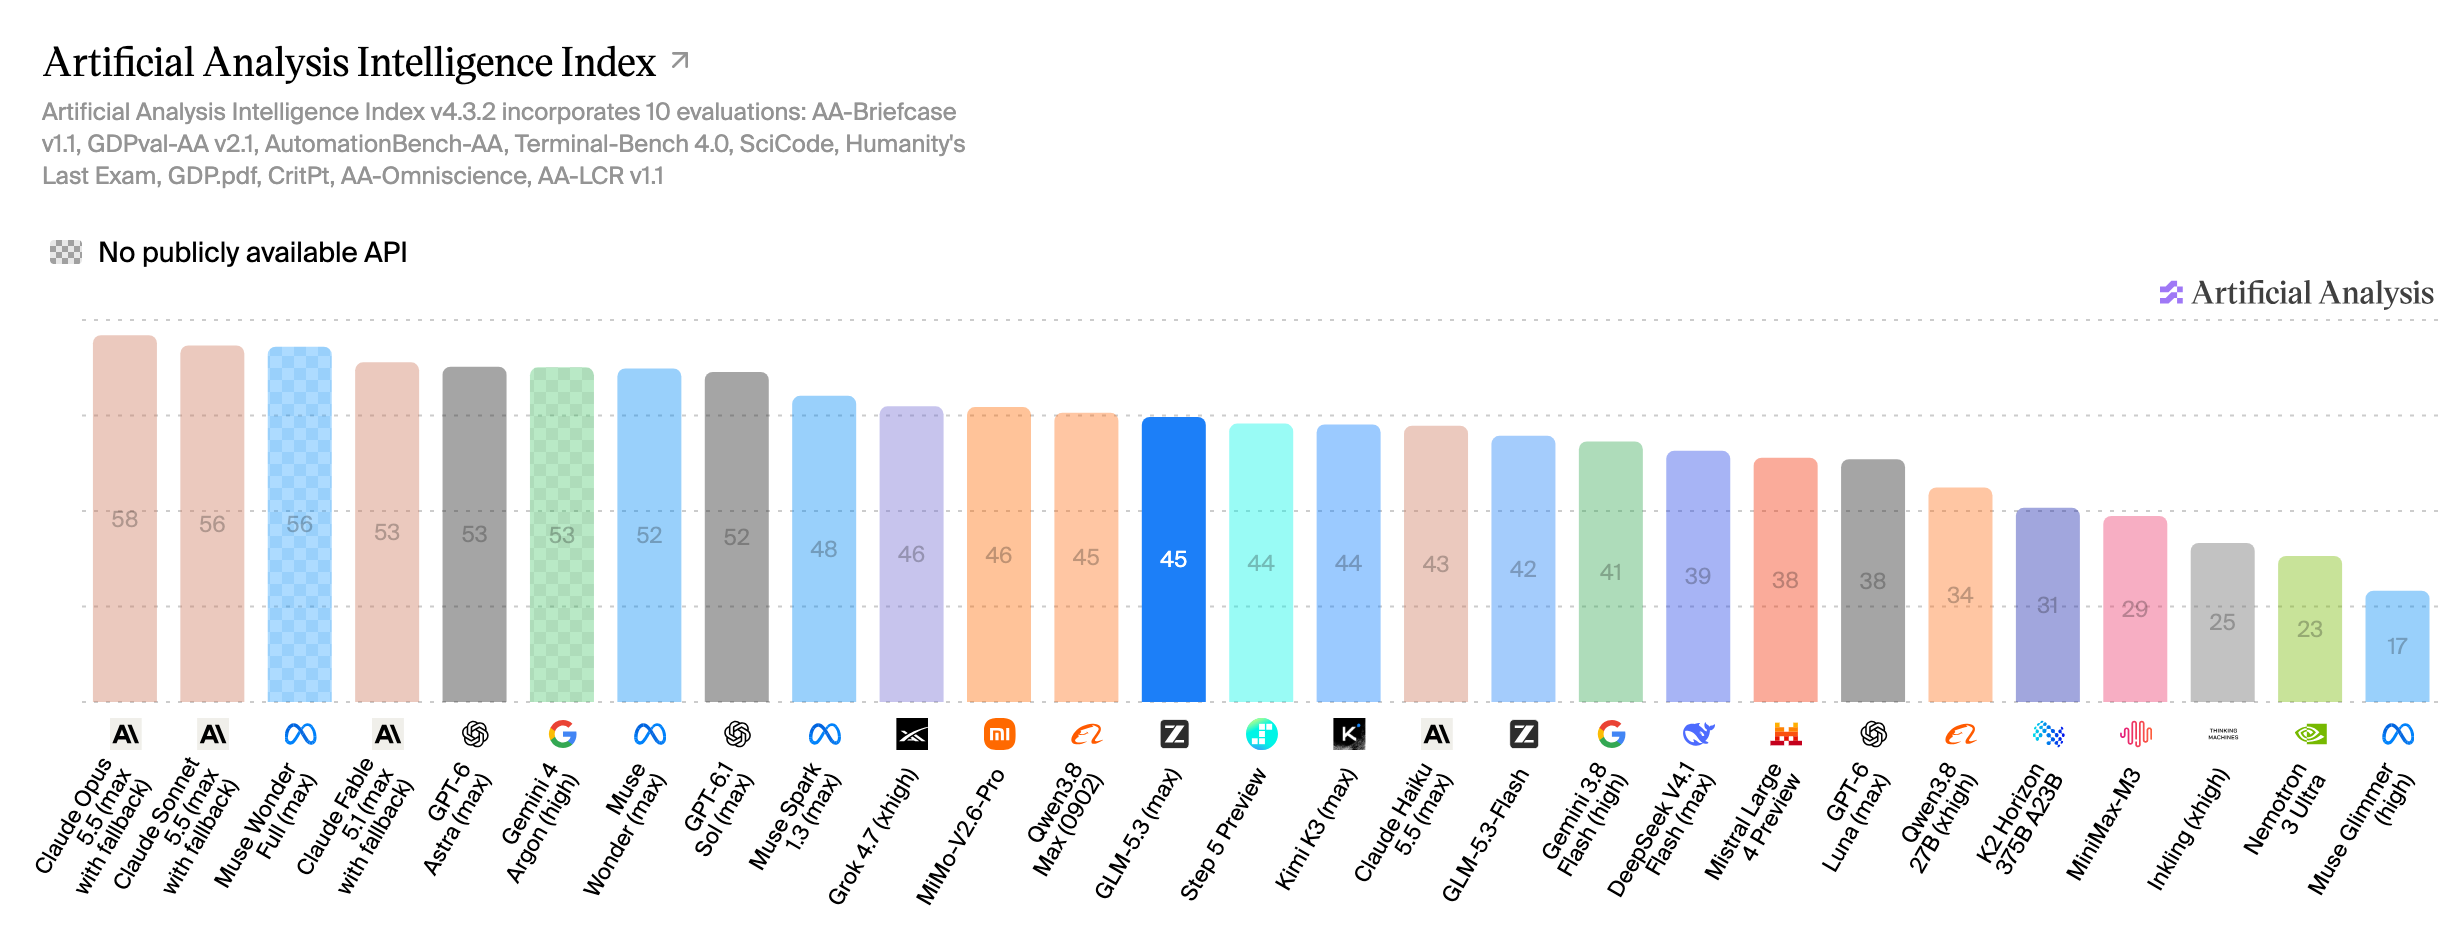
Where GLM 5.3 sits on the Artificial Analysis Intelligence Index
GLM 5.3 costs about $0.057 per average coding-agent request on our measured traffic, at list prices of $1.40 per million input and $4.40 per million output tokens. It is the highest-scoring open-weight model on the tbench.ai Terminal-Bench 4.0 leaderboard, at 41.8%.
Run GLM 5.3 in your agent
Or let the router send each step to the cheapest model that can do it, on providers we vet for price, uptime and speed. Plans from $19 a month.
| Cost at list price | GLM 5.3 |
|---|---|
| Prompt under 100K tokens50% of requests, 87% of input cached | $0.026 |
| Prompt of 100K to 272K39% of requests, 88% of input cached | $0.070 |
| Prompt over 272K tokens11% of requests, 86% of input cached | $0.16 |
| Average request | $0.057 |
| 100 requests | $5.72 |
| Median session16 requests; a session ends after 10 idle minutes | $0.71 |
| A month of regular usemedian of 20 users active on 5+ days | $92.16 |
Each logged request priced at the vendor’s list rates for its own token counts, including cache reads and any higher rate for long prompts. Average output: 698 tokens per request.
| Artificial Analysis | Value | Rank |
|---|---|---|
| Intelligence Index10 evaluations, 0 to 100 | 45 | 12 of 48 |
| Terminal-Bench 4.0agentic coding in a terminal | 41.9% | 10 of 39 |
| Output speedmedian | 69 tokens/s | 31 of 44 |
| Time to first answer tokenincludes thinking time | 32 s | 18 of 44 |
Source: Artificial Analysis (artificialanalysis.ai). Measured variant: GLM-5.3 (Max), speed on Z AI. Fetched October 13, 2026. Rank is among the models on this site, older versions included. Artificial Analysis runs Terminal-Bench 4.0 in its own setup, so its scores differ from the tbench.ai leaderboard.
Z.AI charges $0.26 per million for cache reads, 19% of its input price, where Anthropic and OpenAI charge 5 to 10%. Cache-heavy agent traffic therefore costs more than the list price suggests: GLM 5.3 came out 7% more expensive per request than Claude Sonnet 5.5 despite a 30% lower input price. Reasoning is always on, which adds output tokens.
GLM 5.3 is Z.AI's flagship, a 753B mixture-of-experts model post-trained on the GLM 5.2 base, with a 1M-token context and 128K output. It reached the API on August 14, 2026 and its weights followed on August 29 under a custom GLM 5.3 license. It has the highest open-weight score on the tbench.ai Terminal-Bench 4.0 leaderboard (41.8%), scores 41.9% in Artificial Analysis's own Terminal-Bench 4.0 run and 45 on the Artificial Analysis Intelligence Index, and 95.6 on Scale's SWE-Bench Pro V2. Reasoning is always on, and it outputs about 69 tokens per second. Cache reads cost $0.26 per million, so it costs slightly more per request than Claude Sonnet 5.5 in our measurements ($0.057 vs $0.053). Z.AI also sells smaller Flash and FlashX variants.
Sources: Z.AI docs · Hugging Face · Terminal-Bench 4.0 · SWE-Bench Pro V2 · Artificial Analysis
Coding agents that need open weights and strong agentic scores.
 Best model for Cline
 Best model for Aider
 Best model for Kilo Code
 Best model for OpenCode
 Best model for OpenClaw
 Best model for Hermes
Setting it up? GLM 5.3: model ID, providers and agent config →
The agent matters as much as the model. Which agent gets the most out of GLM 5.3? →
Every model on this page runs on Standard Compute