Where MiniMax M3 sits on the Artificial Analysis Intelligence Index
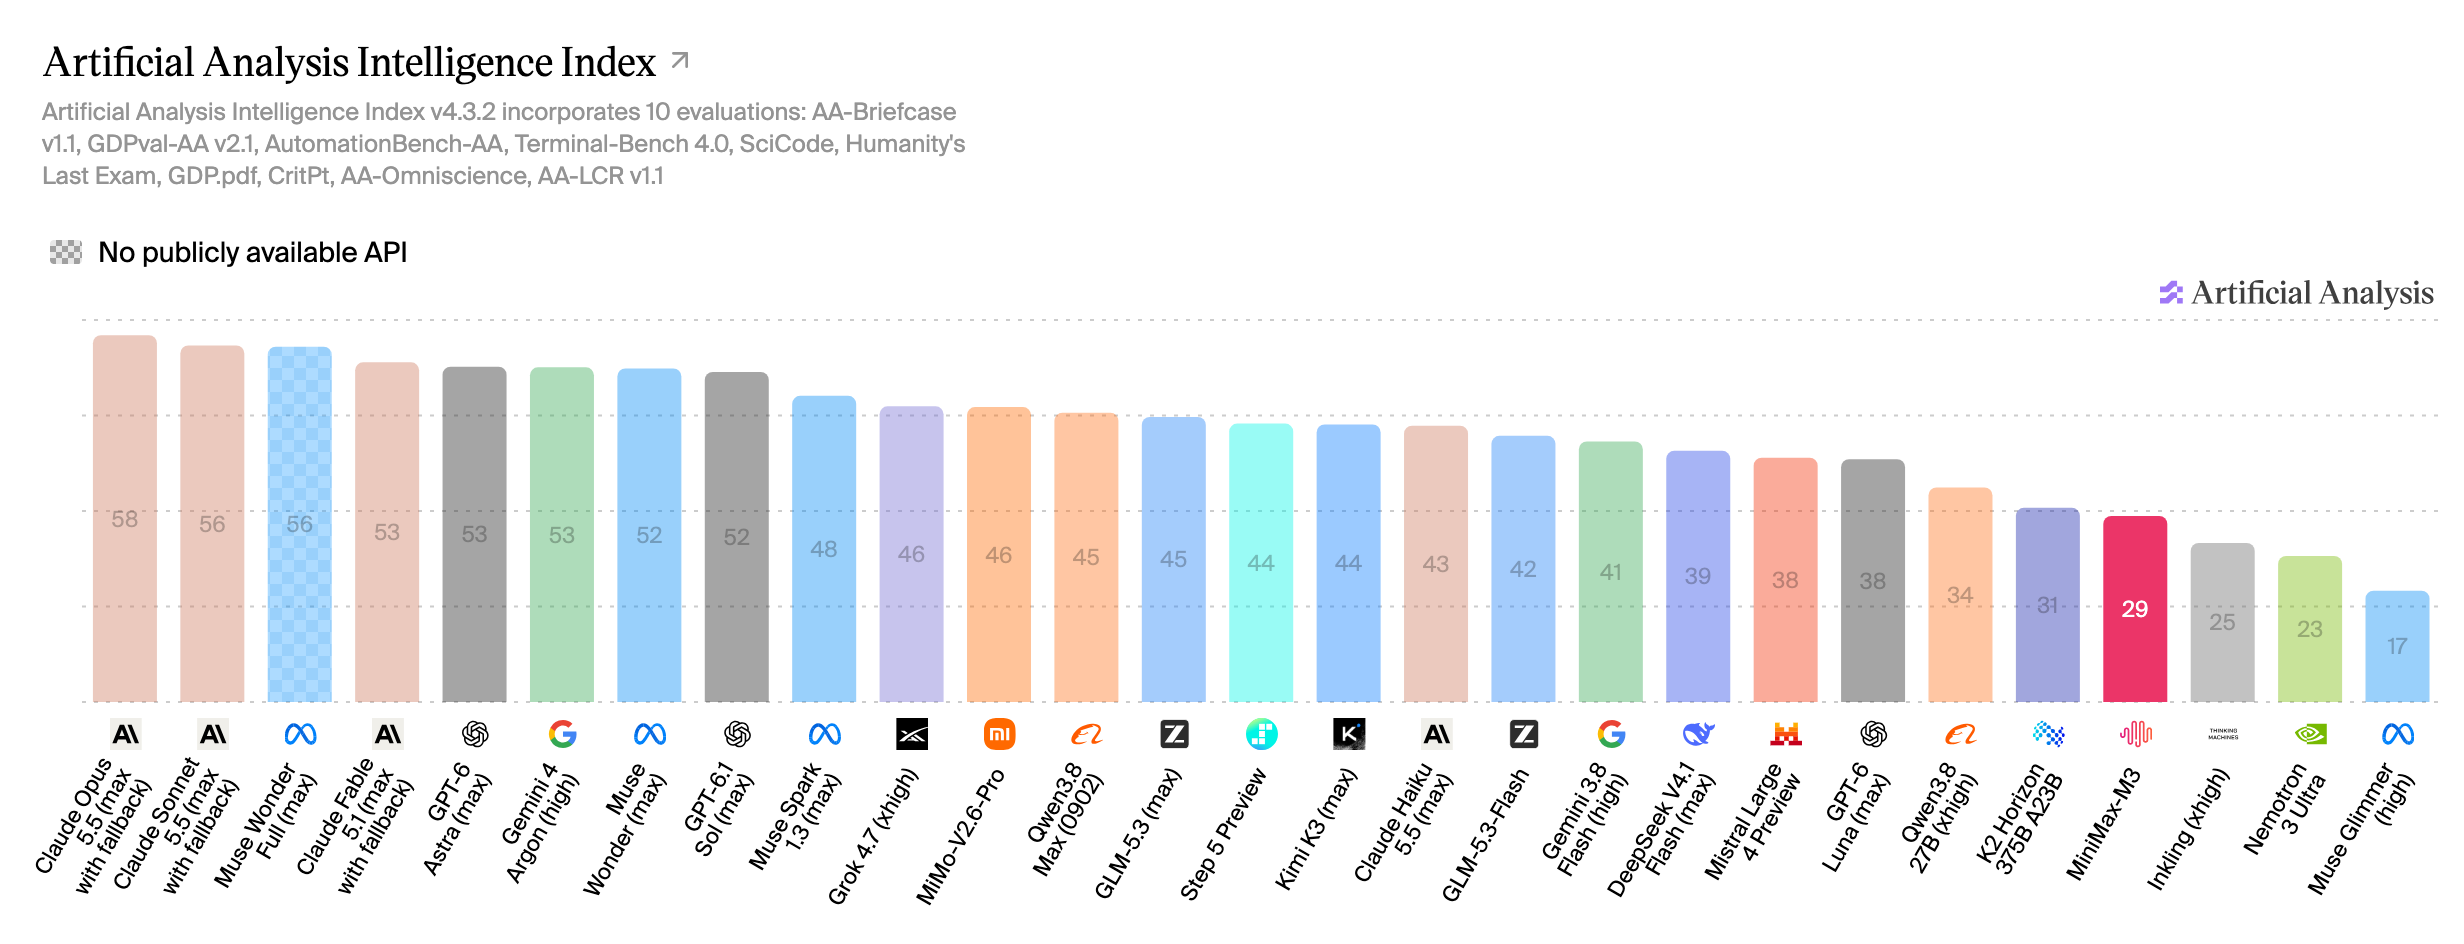
MiniMax M3 costs about $0.013 per average coding-agent request on our measured traffic, at OpenRouter's listed prices of $0.30 per million input and $1.20 per million output tokens. It scores 29 on the Artificial Analysis Intelligence Index, 31st of the 48 models we track. Source: Artificial Analysis (artificialanalysis.ai)
Run MiniMax M3 in your agent
Or let the router send each step to the cheapest model that can do it, on providers we vet for price, uptime and speed. Plans from $19 a month.
| Cost at list price | MiniMax M3 |
|---|---|
| Prompt under 100K tokens50% of requests, 87% of input cached | $0.0060 |
| Prompt of 100K to 272K39% of requests, 88% of input cached | $0.016 |
| Prompt over 272K tokens11% of requests, 86% of input cached | $0.035 |
| Average request | $0.013 |
| 100 requests | $1.29 |
| Median session16 requests; a session ends after 10 idle minutes | $0.16 |
| A month of regular usemedian of 20 users active on 5+ days | $20.98 |
Each logged request priced at the listed rates above for its own token counts, including cache reads and any higher rate for long prompts. Average output: 698 tokens per request.
| Artificial Analysis | Value | Rank |
|---|---|---|
| Intelligence Index10 evaluations, 0 to 100 | 29 | 31 of 48 |
| Terminal-Bench 4.0agentic coding in a terminal | 2.0% | 27 of 39 |
| Output speedmedian | 119 tokens/s | 14 of 44 |
| Time to first answer tokenincludes thinking time | 18 s | 8 of 44 |
Source: Artificial Analysis (artificialanalysis.ai). Measured variant: MiniMax-M3, speed on MiniMax. Fetched October 13, 2026. Rank is among the models on this site, older versions included. Artificial Analysis runs Terminal-Bench 4.0 in its own setup, so its scores differ from the tbench.ai leaderboard.
The price is OpenRouter's listed rate on October 13, 2026, which can be a third-party host's; MiniMax's own API may charge differently. It is weak on long agentic coding tasks (see Terminal-Bench 4.0 above), so a cheap request can turn into more steps and retries.
MiniMax M3 is the June 2026 model in MiniMax's agent-focused open-weight line, with a 1M-token context. MiniMax pitches the line for tool use and long-horizon tasks, but independent results are modest: 29 on the Artificial Analysis Intelligence Index and 2.0% in its Terminal-Bench 4.0 run, at about 118 output tokens per second. At OpenRouter's listed price it costs $0.013 per request in our measurements, about twice DeepSeek V4.1 Flash at peak rates, which scores higher on both boards.
Sources: Artificial Analysis
Agents that need an open-weight model with a 1M context.
 Best model for OpenClaw
 Best model for Hermes
 Best model for Cline
 Best model for OpenCode
 Best model for Aider
Setting it up? MiniMax M3: model ID, providers and agent config →
The agent matters as much as the model. Which agent gets the most out of MiniMax M3? →
Every model on this page runs on Standard Compute