Where Step 5 sits on the Artificial Analysis Intelligence Index
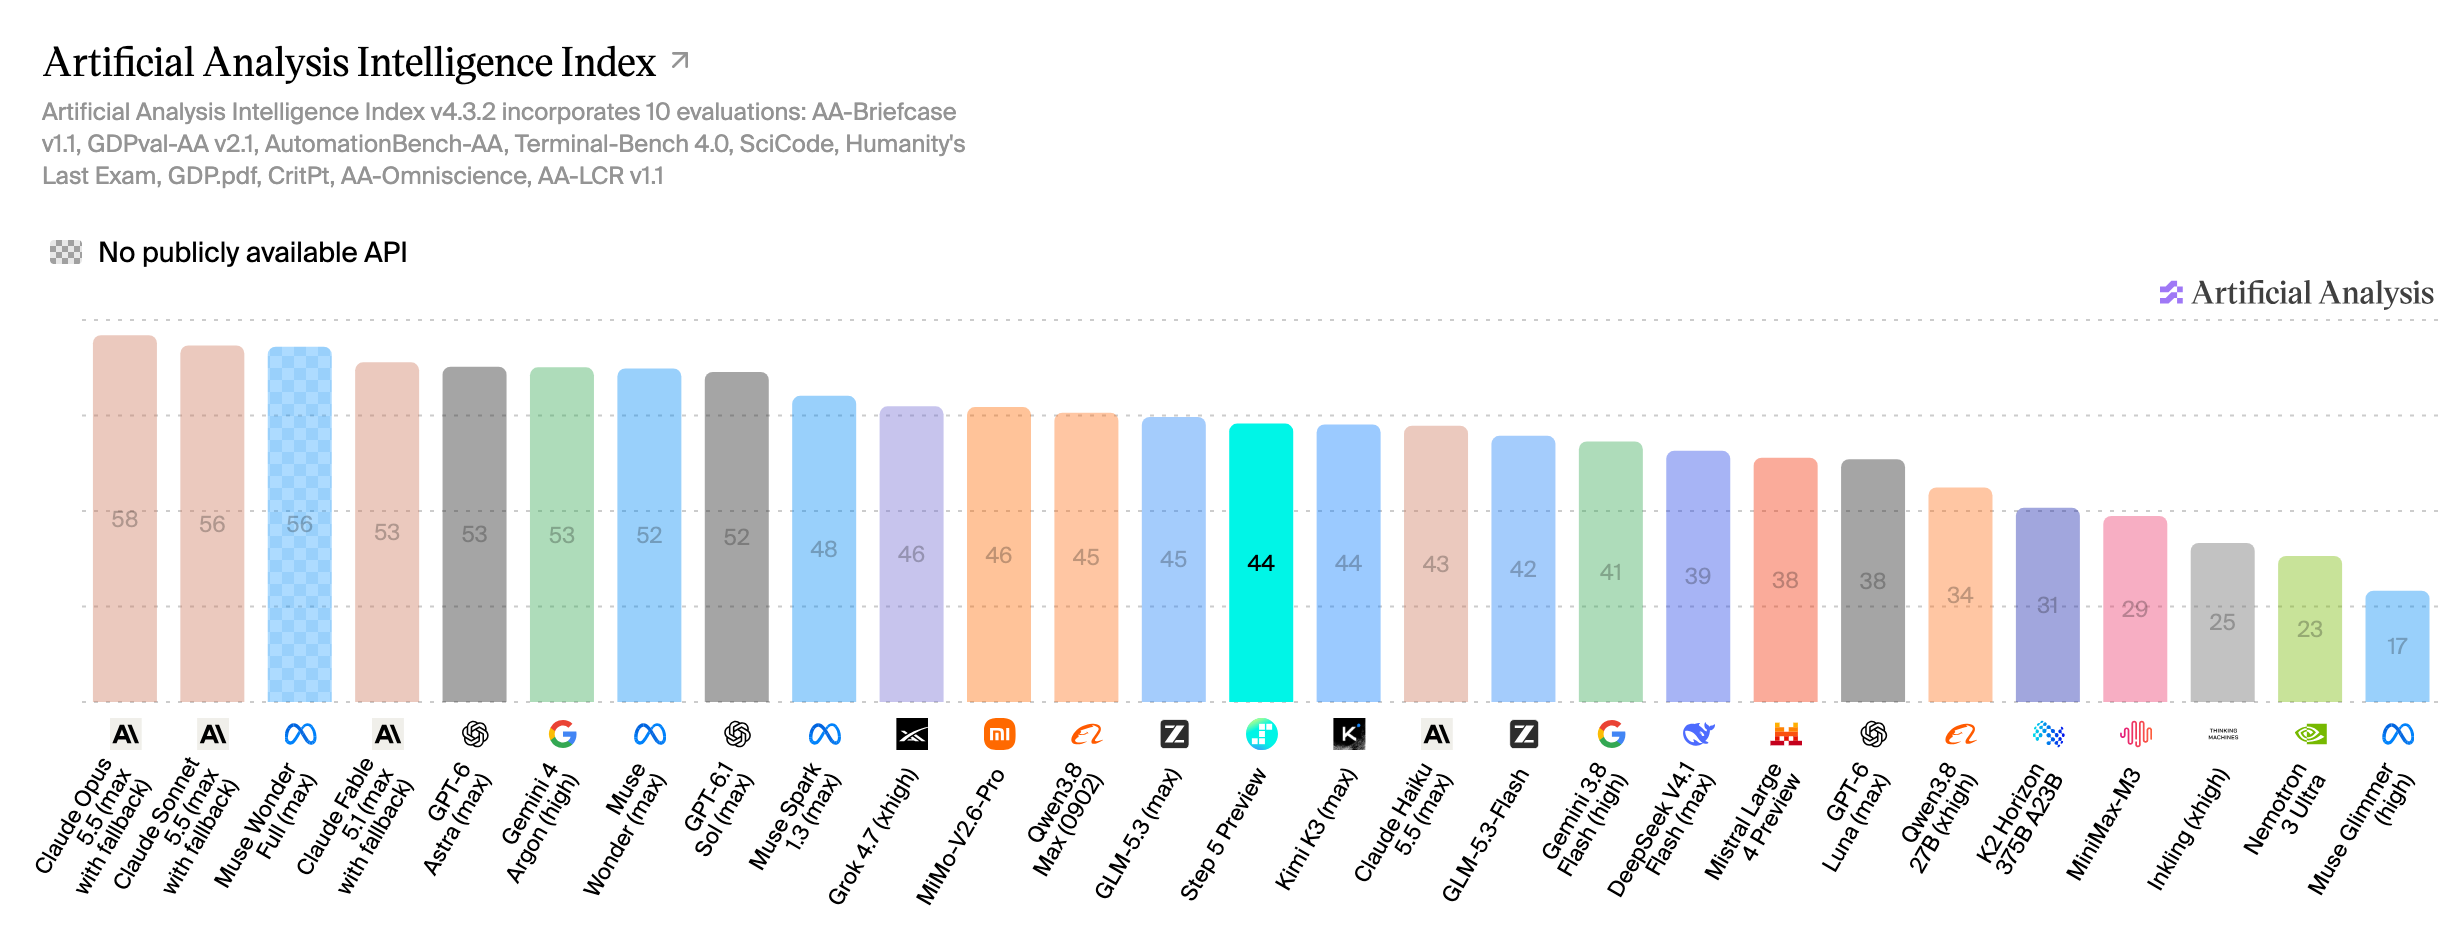
Step 5 Preview costs about $0.025 per average coding-agent request on our measured traffic, at list prices of $1 per million input and $2.70 per million output tokens. It scores 44 on the Artificial Analysis Intelligence Index, 13th of the 48 models we track. Source: Artificial Analysis (artificialanalysis.ai)
Run current Claude, GPT, Gemini and open models in your agent from $19/month
See plans| Cost at list price | Step 5 |
|---|---|
| Prompt under 100K tokens50% of requests, 87% of input cached | $0.012 |
| Prompt of 100K to 272K39% of requests, 88% of input cached | $0.030 |
| Prompt over 272K tokens11% of requests, 86% of input cached | $0.069 |
| Average request | $0.025 |
| 100 requests | $2.48 |
| Median session16 requests; a session ends after 10 idle minutes | $0.33 |
| A month of regular usemedian of 20 users active on 5+ days | $35.48 |
Each logged request priced at the vendor’s list rates for its own token counts, including cache reads and any higher rate for long prompts. Average output: 698 tokens per request.
| Artificial Analysis | Value | Rank |
|---|---|---|
| Intelligence Index10 evaluations, 0 to 100 | 44 | 13 of 48 |
| Terminal-Bench 4.0agentic coding in a terminal | 33.3% | 13 of 39 |
| Output speedmedian | 90 tokens/s | 25 of 44 |
| Time to first answer tokenincludes thinking time | 25 s | 15 of 44 |
Source: Artificial Analysis (artificialanalysis.ai). Measured variant: Step 5 Preview, speed on StepFun. Fetched October 13, 2026. Rank is among the models on this site, older versions included. Artificial Analysis runs Terminal-Bench 4.0 in its own setup, so its scores differ from the tbench.ai leaderboard.
Cost per request is not cost per finished task: a weaker model can need more steps for the same work, so test it on a task from your own repository.
Step 5 Preview is StepFun's flagship model for agent work, on OpenRouter since October 8, 2026 and served there by StepFun. It is a sparse mixture-of-experts model with 27B active and 600B total parameters, reads text, images and video, and has a 1M-token context with 64K output. Artificial Analysis scores it 44 on its Intelligence Index and 33.3% in its Terminal-Bench 4.0 run, ahead of Gemini 3.8 Flash on both, at about 90 output tokens per second. In our measurements it costs $0.025 per request, about half of Gemini 3.8 Flash. Cline added it to its free model list on October 13. It is still a preview.
Sources: OpenRouter listing · Artificial Analysis · Cline v4.1.24 release notes
Mid-priced agent loops that want more capability than a Flash-class model.
The agent matters as much as the model. Which agent gets the most out of Step 5? →
Current Claude, GPT, Gemini and open models are included with Standard Compute
 Best model for Cline
 Best model for OpenCode
 Best model for OpenClaw
 Best model for Hermes
 Best model for Kilo Code