Where DeepSeek V4.1 Flash sits on the Artificial Analysis Intelligence Index
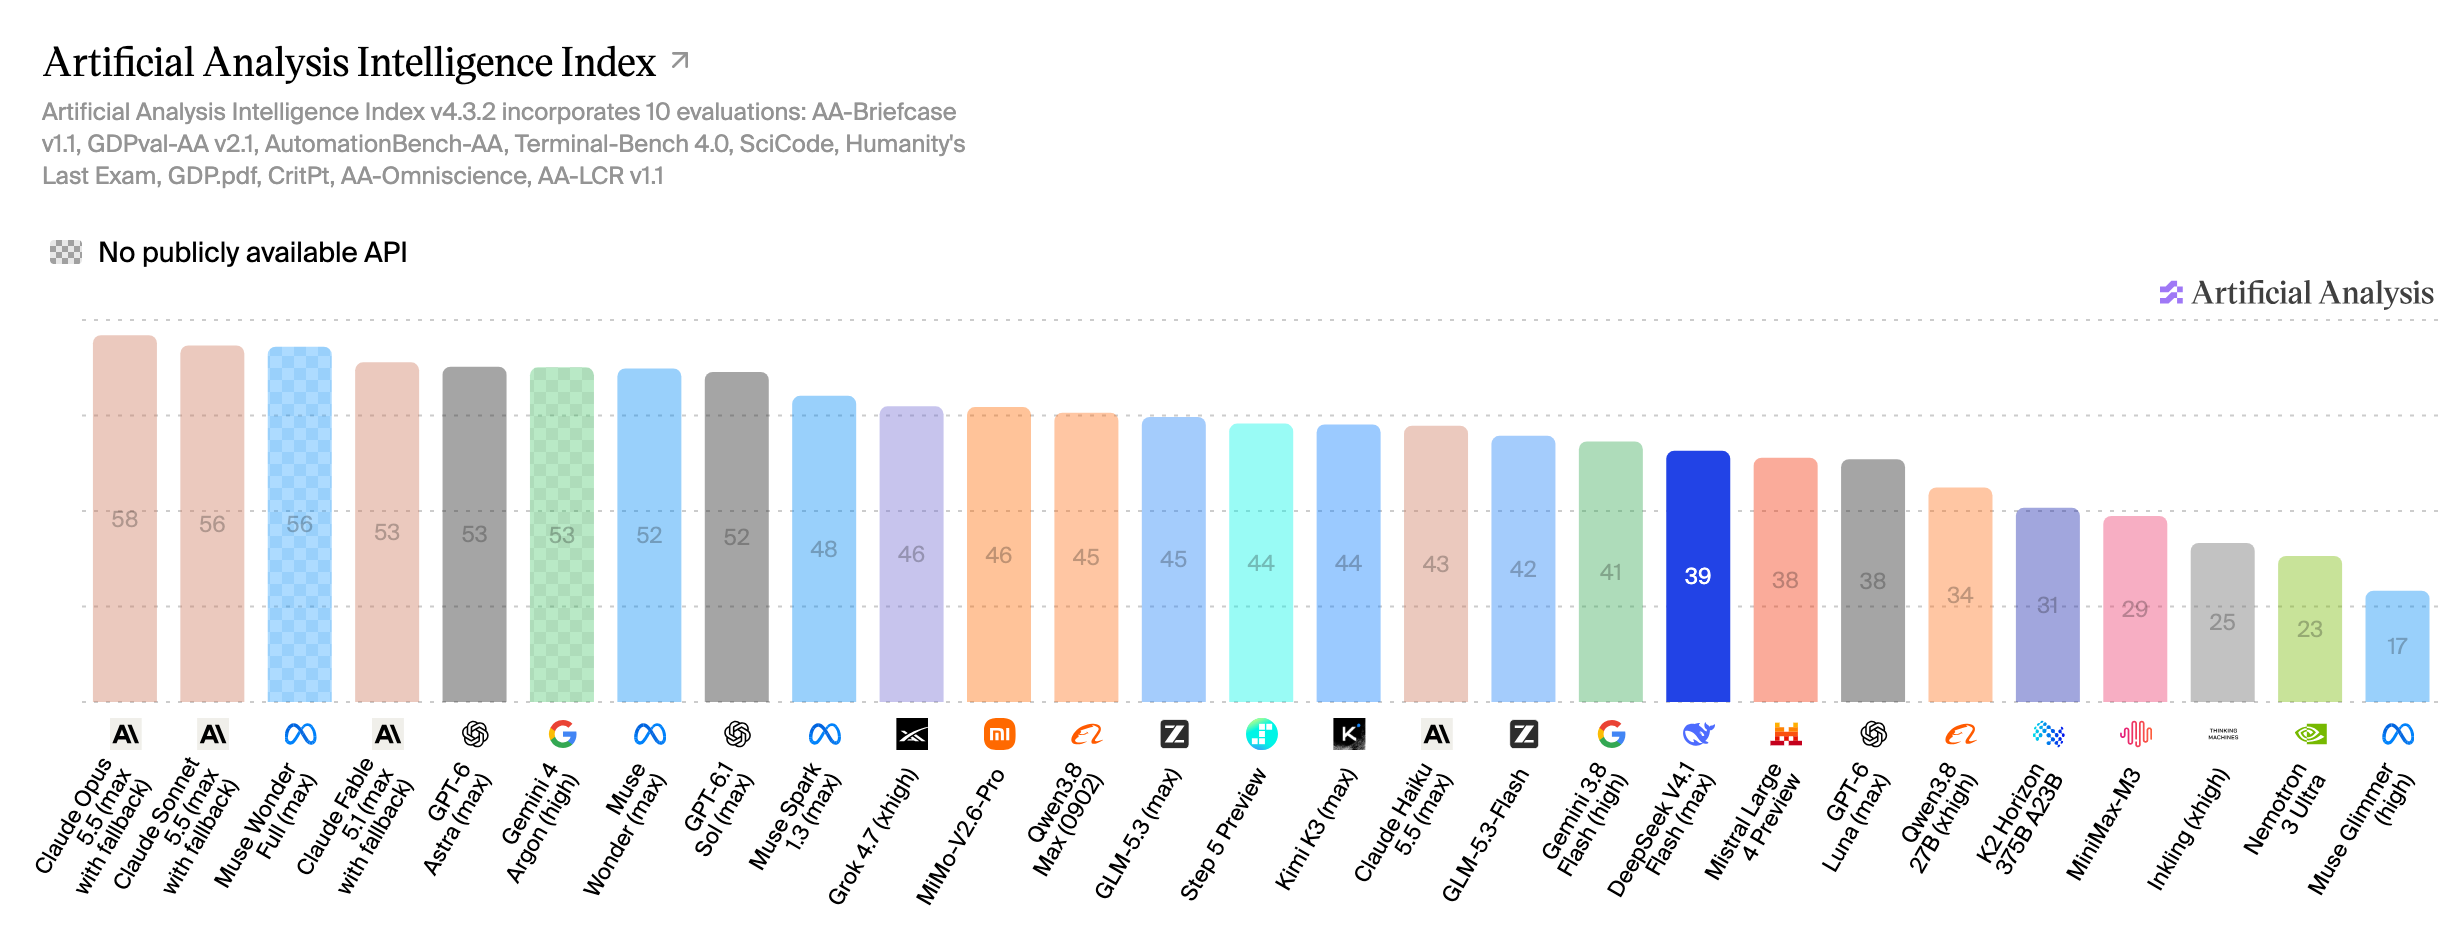
DeepSeek V4.1 Flash costs about $0.0067 per average coding-agent request on our measured traffic, at list prices of $0.30 per million input and $1.20 per million output tokens. It handles high-volume agent steps and scores 39 on the Artificial Analysis Intelligence Index. (Source: Artificial Analysis (artificialanalysis.ai))
Run DeepSeek V4.1 Flash in your agent from $19/month
See plans| Cost at list price | DeepSeek V4.1 Flash |
|---|---|
| Prompt under 100K tokens50% of requests, 87% of input cached | $0.0033 |
| Prompt of 100K to 272K39% of requests, 88% of input cached | $0.0080 |
| Prompt over 272K tokens11% of requests, 86% of input cached | $0.018 |
| Average request | $0.0067 |
| 100 requests | $0.67 |
| Median session16 requests; a session ends after 10 idle minutes | $0.091 |
| A month of regular usemedian of 20 users active on 5+ days | $9.13 |
Each logged request priced at the vendor's list rates for its own token counts, including cache reads and any higher rate for long prompts. Average output: 698 tokens per request.
These are DeepSeek's peak-hour rates (01:00 to 04:00 and 06:00 to 10:00 UTC on weekdays). The rest of the time it costs half, $0.33 per 100 requests. At peak rates GPT-6 Luna is cheaper per request ($0.0041 vs $0.0067); off-peak, DeepSeek is.
DeepSeek V4.1 Flash is a 552B mixture-of-experts model released September 10, 2026 with open weights under the MIT license and a 1M-token context. It is the most-used model on OpenCode's public usage board by tokens as of October 13, 2026. Independent scores put it below the frontier: 39 on the Artificial Analysis Intelligence Index, #23 on LMArena WebDev, at about 199 output tokens per second. DeepSeek reports 74.2% on DeepSWE v1.1 and 31.2% on Terminal-Bench 4.0. DeepSeek's API now serves V4 Flash requests with V4.1 Flash, and charges half price outside its peak hours.
Sources: DeepSeek announcement · Hugging Face · Artificial Analysis · OpenCode usage
Cheap, high-volume open-weight agent work.
The agent matters as much as the model. Which agent gets the most out of DeepSeek V4.1 Flash? →
Every model on this page is included with Standard Compute
 Best model for Cline
 Best model for OpenCode
 Best model for OpenClaw
 Best model for Hermes
 Best model for Kilo Code
 Best model for Continue