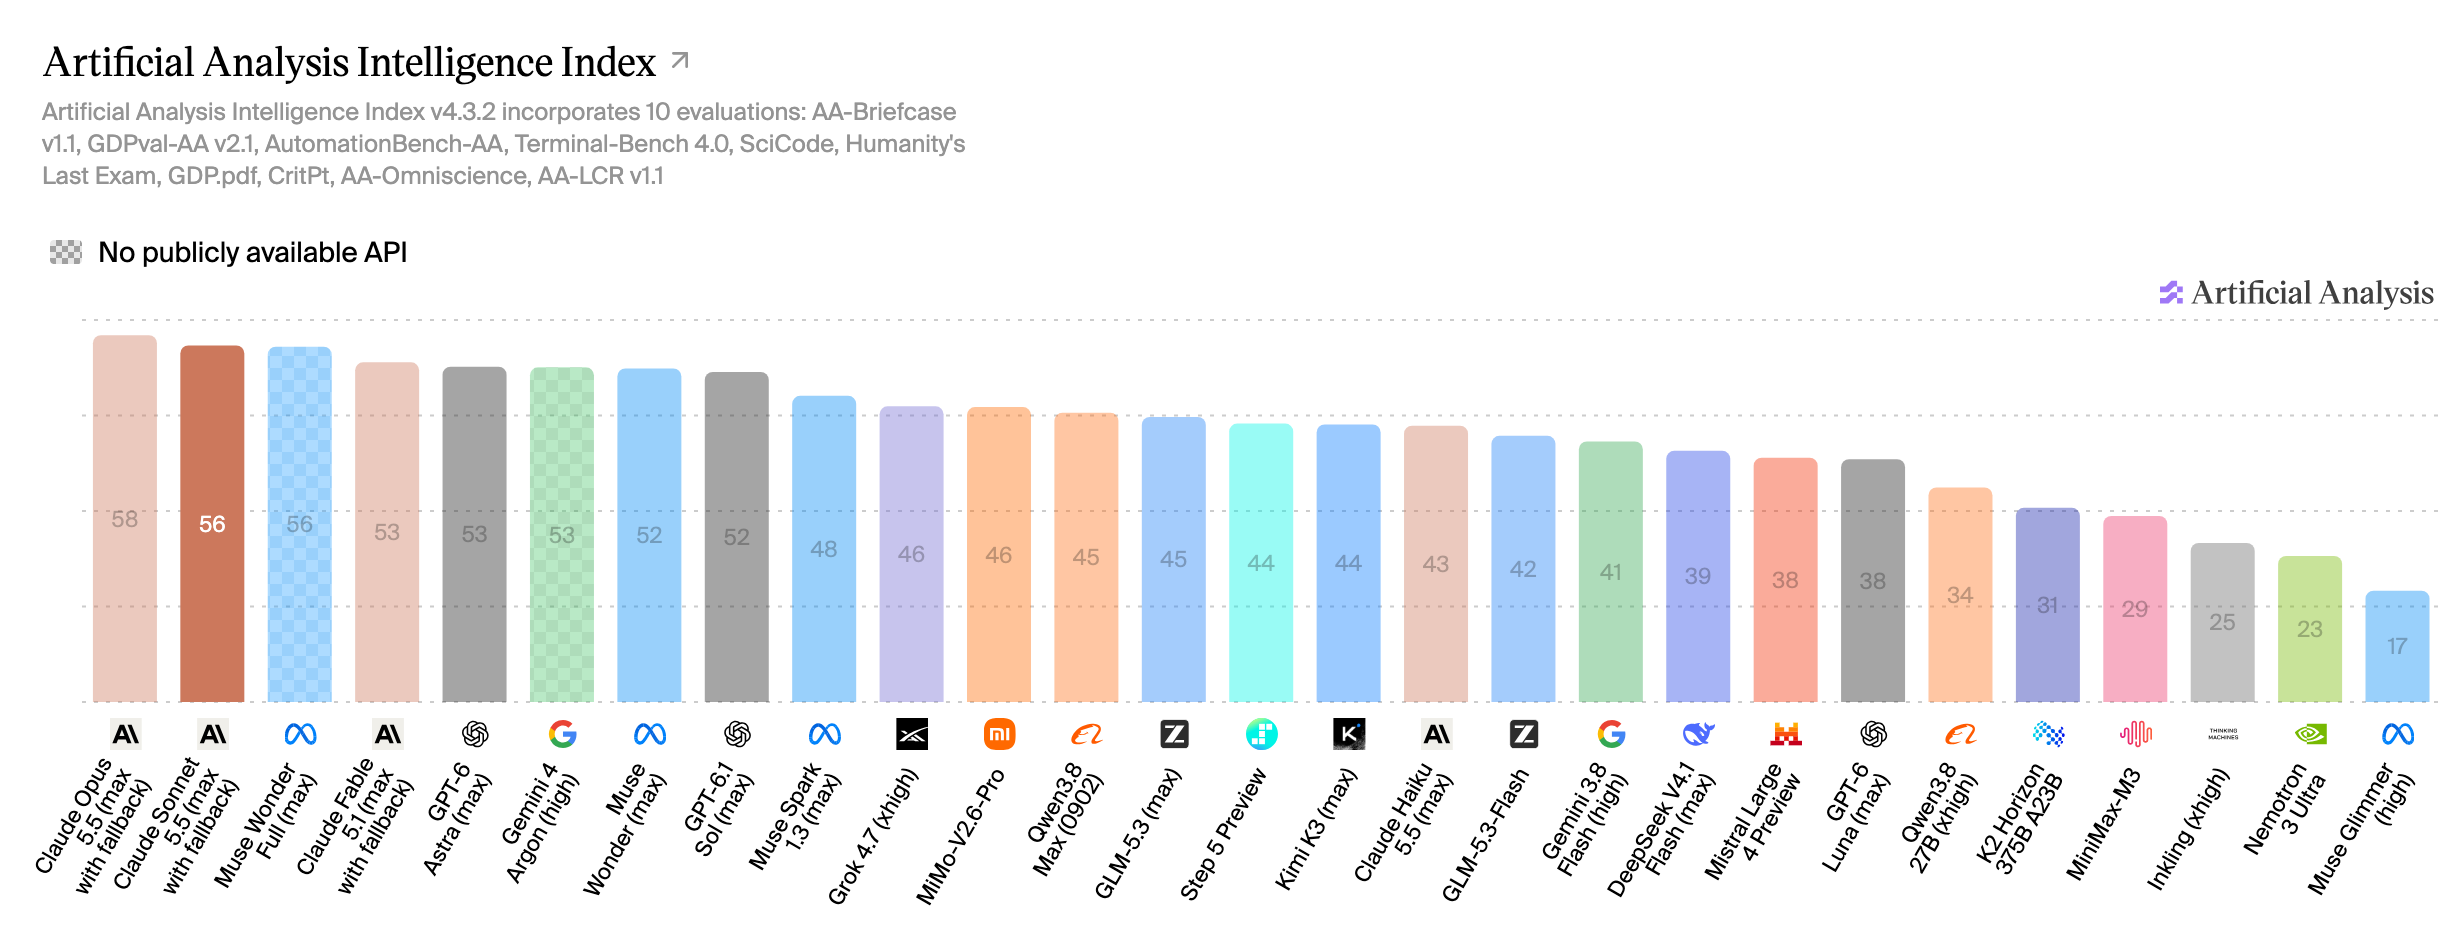
Where Sonnet 5.5 sits on the Artificial Analysis Intelligence Index
Claude Sonnet 5.5 costs about $0.053 per average coding-agent request on our measured traffic, at list prices of $2 per million input and $10 per million output tokens. It is the everyday coding default, second only to Opus 5.5 on the tbench.ai Terminal-Bench 4.0 leaderboard at 61.8%.
Run Claude Sonnet 5.5 in your agent
Or let the router send each step to the cheapest model that can do it, on providers we vet for price, uptime and speed. Plans from $19 a month.
| Cost at list price | Sonnet 5.5 |
|---|---|
| Prompt under 100K tokens50% of requests, 87% of input cached | $0.026 |
| Prompt of 100K to 272K39% of requests, 88% of input cached | $0.064 |
| Prompt over 272K tokens11% of requests, 86% of input cached | $0.14 |
| Average request | $0.053 |
| 100 requests | $5.33 |
| Median session16 requests; a session ends after 10 idle minutes | $0.74 |
| A month of regular usemedian of 20 users active on 5+ days | $77.42 |
Each logged request priced at the vendor’s list rates for its own token counts, including cache reads and any higher rate for long prompts. Average output: 698 tokens per request.
| Artificial Analysis | Value | Rank |
|---|---|---|
| Intelligence Index10 evaluations, 0 to 100 | 56 | 2 of 48 |
| Terminal-Bench 4.0agentic coding in a terminal | 63.6% | 1 of 39 |
| Output speedmedian | 136 tokens/s | 9 of 44 |
| Time to first answer tokenincludes thinking time | 7.3 min | 43 of 44 |
Source: Artificial Analysis (artificialanalysis.ai). Measured variant: Claude Sonnet 5.5 (Max, Default Fallback), speed on Anthropic. Fetched October 13, 2026. Rank is among the models on this site, older versions included. Artificial Analysis runs Terminal-Bench 4.0 in its own setup, so its scores differ from the tbench.ai leaderboard.
These figures assume 87% of input is read from cache at $0.10 per million, as in our traffic. A request that misses the cache (a new task, an edited system prompt, or a long pause) pays $2 per million on every input token, twenty times more, and writing the cache costs 1.25x input.
Claude Sonnet 5.5 is the mid-tier Claude, released September 28, 2026 as a faster, lower-cost complement to Opus 5.5. It scores close to the flagship: 56 on the Artificial Analysis Intelligence Index against Opus 5.5's 58, and 63.6% in Artificial Analysis's Terminal-Bench 4.0 run, the highest of the models on this hub. On the tbench.ai leaderboard it is #2 at 61.8%, and it is #3 on LMArena's WebDev board. Anthropic reports 70.6% on Terminal-Bench 4.0 against 10.3% for Sonnet 5, and says it runs over 30% faster and costs up to 30% less than its predecessor. It has a 1M-token context window and 128K output; effort defaults to high on the API and medium in Claude Code.
Sources: Anthropic announcement · Artificial Analysis · Terminal-Bench 4.0 · SWE-Bench Pro V2
The everyday default for coding agents, escalating to Opus 5.5 for the hardest tasks.
 Best model for Claude Code
 Best model for Cline
 Best model for Aider
 Best model for Cursor
 Best model for OpenCode
 Best model for OpenClaw
Not sure which Claude to run? Best Claude model in 2026: Opus vs Sonnet vs Haiku →
Setting it up? Claude Sonnet 5.5: model ID, providers and agent config →
The agent matters as much as the model. Which agent gets the most out of Sonnet 5.5? →
Every model on this page runs on Standard Compute